Efficient Memory Utilization in AI through Full Stack Codesign
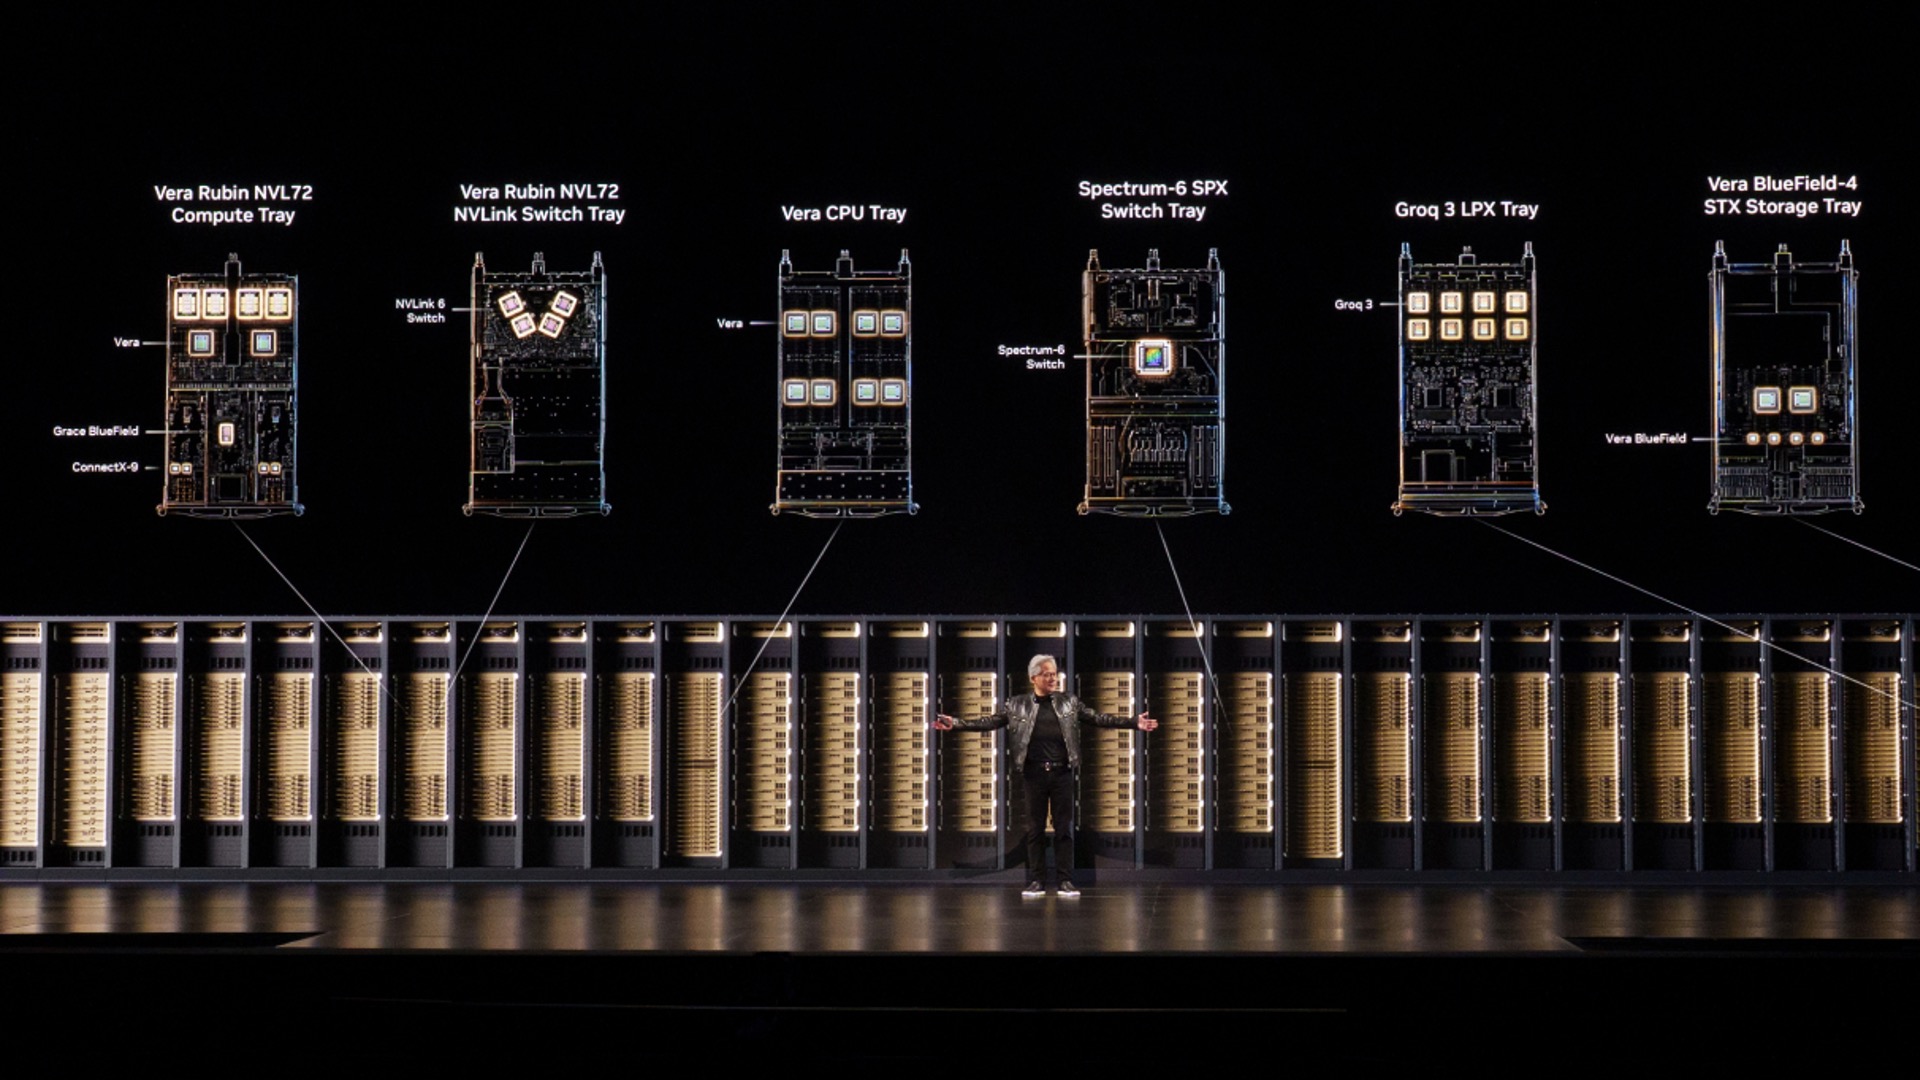
The growth of larger AI models and agentic applications puts increasing pressure on GPU memory. At the same time, these memory components are limited in availability and prices are rising. NVIDIA responds to these challenges by closely collaborating with memory partners and quickly adopting new technologies, such as HBM3e and HBM4. However, the company does not implement a simple solution by adding more memory to the GPUs; instead, it focuses on a full stack codesign. This means that NVIDIA designs GPUs, CPUs, networks, storage, and software together to enhance memory efficiency at every level.
The use of memory in an AI factory is based on a hierarchy of memory and storage, where high bandwidth memory (HBM) forms the fastest and most expensive layer, followed by CPU memory and local SSDs. The effectiveness of each byte of memory heavily depends on how well these layers are utilized. NVIDIA's approach concentrates on optimizing storage requirements by strategically placing data and applying efficient techniques that reduce the need for memory.
With developments like the NVFP4 format and collaboration with various partners focused on contextual memory management, NVIDIA reduces the burden on HBM by shrinking model weights and KV-cache. This provides more space for the active storage of context data and allows for efficient usage via the Dynamo inference software. This system manages the KV-cache as a shared tool that promotes collaboration between GPU and CPU memory.
The results are remarkable, as despite limited growth in HBM capacity per GPU, throughput per dollar significantly increases across various platforms. By combining elite memory management with a smart structure, AI factories can deliver more valuable data within their power budget. NVIDIA's full stack codesign not only results in higher throughput but also lowers the cost per token, which is crucial for the future development of AI applications.
Read the full article from Nvidia.
Gerelateerde artikelen

Axiom Math and the Future of Mathematical Verification
Axiom Math, a startup focused on ensuring integrity within mathematics, responds to the increasing influence of unregulated artificial intelligence (AI) currently flooding mathematical proofs. This gr...
Tech Festival
05 November 2026
Chris Alexiuk: The Wizard of Open AI Models
Chris Alexiuk, senior product research engineer at NVIDIA, is a passionate advocate for open source AI. He emphasizes that transparency is essential for the development of good AI and that open source...
Tech Festival
05 November 2026
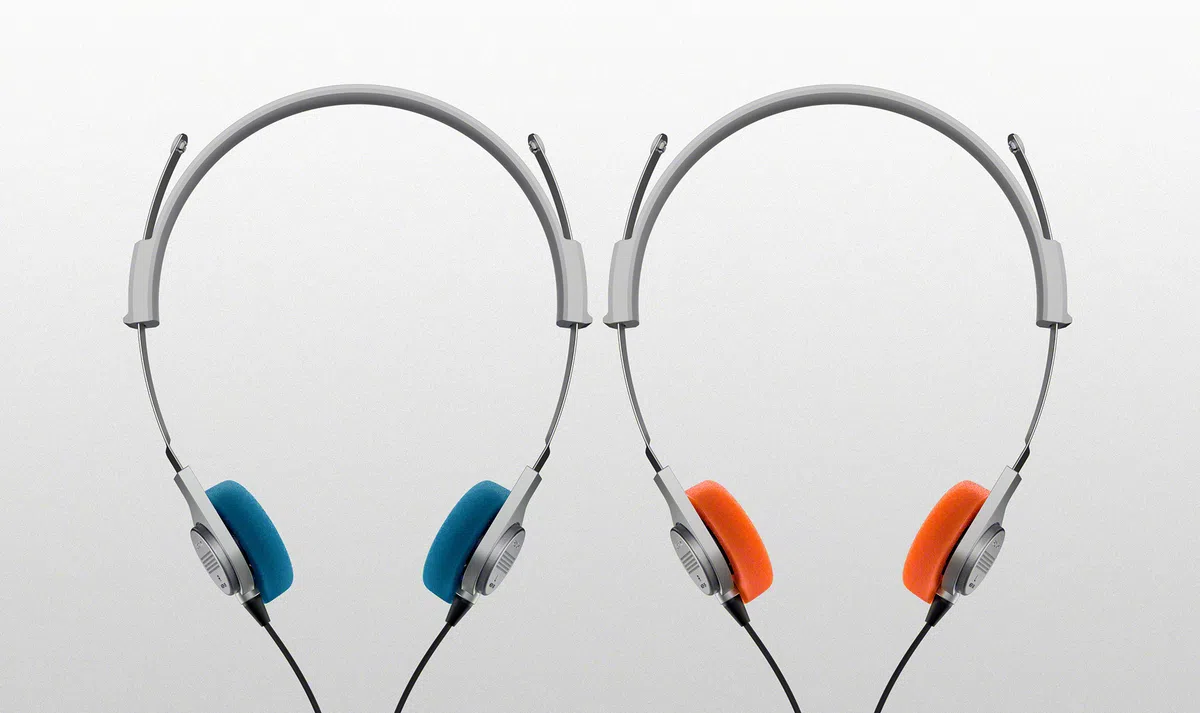
Sony launches modern variant of classic Walkman headphones
Sony has recently introduced a modern variant of its iconic MDR-3 headphones, which were originally released in 1979 alongside the first Walkman. The new version, the MDR-3R, combines nostalgia with c...
Tech Festival
05 November 2026