Compact 32MB Speech Model by Underdog

Underdog has recently presented a new speech model that is remarkable due to its modest size of just 32MB. This model is capable of generating not only speech but also music. This opens up new possibilities for applications in speech-driven technology and creative projections, without requiring large amounts of storage space.
Underdog's focus is on efficiently developing models that can deliver powerful performance at the same time. The impression the model leaves testifies to the technological advancements in the field of artificial intelligence, even with limited resources. At a time when many AI models demand huge amounts of data, Underdog's innovation offers a refreshing approach that is particularly appealing to organizations with smaller infrastructures.
With the ability to combine speech and music, the model can find interesting applications across various sectors, such as entertainment, education, and healthcare. The small file size makes it more accessible to a broader range of developers and companies looking to experiment with speech and music technologies, without having to worry about high costs or complex implementation.
Underdog's presentation provides an indication of the future of AI technologies: increasingly sophisticated yet more accessible to a wider user base. This could ultimately lead to more innovation and creativity in the sector, as more professionals gain access to powerful tools that can enhance their work.
Read the full article from Techcrunch.
Gerelateerde artikelen
Anthropic accelerates AI development through self-learning systems
AI company Anthropic has recently made significant progress in the development of artificial intelligence, now achieving in one year the same amount of progress that previously took two years. This re...
Tech Festival
06 November 2026
Amazon introduces text feature for Alexa
Amazon has announced that it will soon be possible to send text messages to Alexa to get help with shopping. This feature will be rolled out to millions of users in the coming weeks. This marks an imp...
Tech Festival
06 November 2026
Return of the Glowing Logo in MacBook Pro
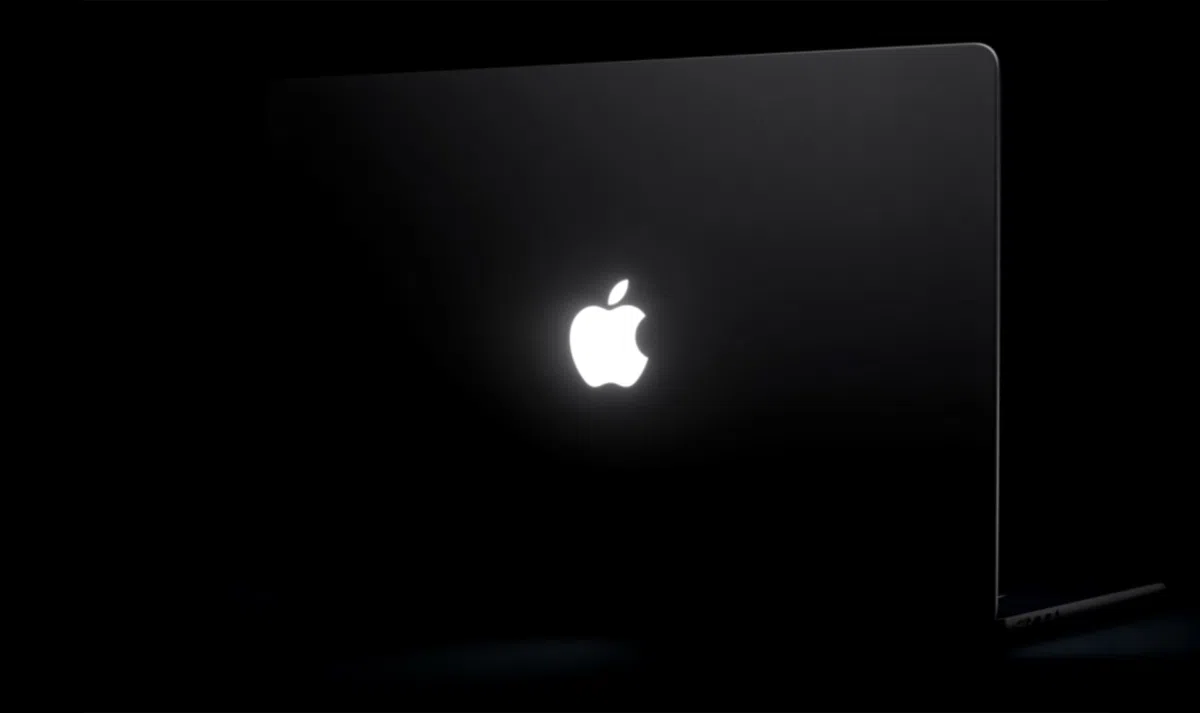
Apple has recently brought back the glowing logo on the new MacBook Pro, featuring the PROLED XDR display. After a decade-long absence, this reintroduction offers tech enthusiasts something to look fo...
Tech Festival
06 November 2026